Orchestrate Real-Time Data Streams at Scale
Ditch brittle ETL batch jobs and locked-in iPaaS. layline.io's reactive engine turns chaotic event streams into reliable, scalable dataflows—so your devs build fast, and your ops run forever.
Platform Capabilities
Built for real-time at scale, designed for developer velocity
Infinite horizontal scale.
Scale from 1K to 10M+ events/second without code changes. Add nodes to your cluster and watch throughput grow linearly. Cluster mesh distributes workloads across regions, zones, or edge locations. Auto-scaling policies adjust capacity in real-time based on traffic patterns.
Example scaling pattern. Actual performance depends on workload complexity, data volume, and infrastructure.

Low-latency event processing.
Reactive Engine processes events in single-digit milliseconds with predictable latency. Backpressure handling prevents cascading failures when traffic spikes—events flow through gracefully instead of crashing your pipeline. Hot-reload config changes without restarting containers.
Build pipelines in hours, not weeks.
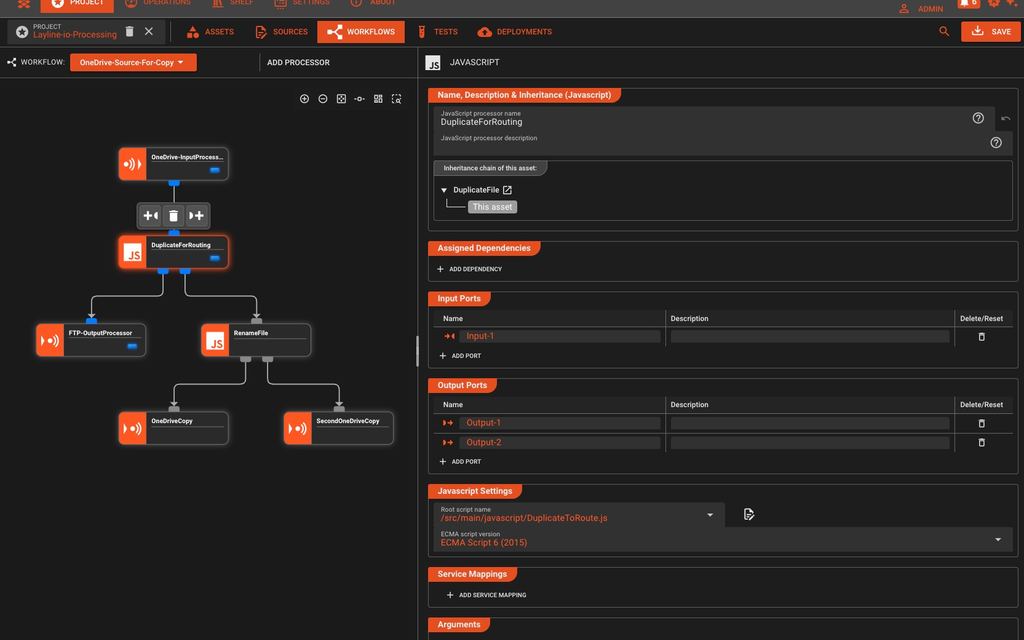
Visual workflow editor accelerates pipeline development—drag, drop, configure your data flows in minutes. When you need custom logic, drop in JavaScript or Python processors seamlessly. Manage multiple deployment targets with environment-specific parameters—all within a single project. Manage configs with your favorite version control system.


Carrier-grade reliability built-in.
Zero-downtime upgrades, exactly-once delivery guarantees, and automatic failover. Built-in audit trails track every event from source to destination. Real-time observability with Prometheus metrics support means you catch issues before customers do.
Developer Experience
Visual workflows meet code flexibility—build pipelines that scale with your team
Visual Workflow Builder
Drag-and-drop processors, configure properties, and connect flows—build complex pipelines with minimal code
- Drag-and-drop visual pipeline design
- Live validation with instant error feedback
- JSON configs and native script files for version control
- All project files in standard formats (JSON, JS, Python)
Business Logic in JavaScript or Python
Drop in scripts when you need custom transformations, complex validations, or external API calls
Event Enrichment
Add geolocation data, user profiles, or lookup values from external sources
Fraud Detection
Apply ML models or rule-based logic to flag suspicious transactions
On the Fly Assembly Counting
Track and count message assemblies in real-time with dynamic counters
Custom Transformation
Reshape data structures, apply business rules, or normalize formats
Work with any Data Format
Parse structured formats from simple CSV to complex binary formats by configuration. Ready parsers for XML and ASN.1
- Flexible definition of data formats. No hard coded schemas.
- Schema validation with detailed error messages
- Convert between formats on-the-fly
- Format engines for XML, ASN.1, structured ASCII, binary
Test & Debug with Real Data
Message sniffing, tests, and comprehensive logging make debugging production issues straightforward
- Sniff live messages from any workflow and processing step
- Step-through Script execution with breakpoints
- Investigate issues with detailed logs and error reports
- Output detailed processing info for troubleshooting
Version Control Ready
All configs in JSON and native scripts—diff, merge, and track changes with any VCS
- JSON configuration files for all projects
- Native script files (JavaScript, Python)
- Use Git, SVN, or any version control system
Near-instant Hot Reload
Deploy config, activate, see results—no container restarts, no downtime
- Instant feedback on config changes
- Test in dev, promote to prod seamlessly
- Switch back to previous configurations instantly
Technical Architecture
Reactive streams, distributed processing, and developer-first design
How It All Works Together
layline.io orchestrates data flow from any source to any destination using a reactive, event-driven architecture. Events flow through processors that transform, enrich, aggregate, and route data—all with backpressure handling and exactly-once delivery guarantees.
Kafka
REST APIs
Databases
layline.io Reactive Engines
Data Lakes
Analytics
Webhooks
Reactive Streams
Pekko actors handle backpressure and asynchronous processing
Processors
Mapping and filtering processors plus custom JavaScript/Python logic
Error Handling
Transaction control with commit/rollback support
Reactive Streams with Apache Pekko
Built on battle-tested Pekko actors for non-blocking, asynchronous event processing
Backpressure Handling
Downstream slow? No problem. Reactive streams automatically signal upstream to slow down, preventing memory overflow and cascading failures.
Error Handling & Recovery
Transaction control with commit/rollback support ensures data integrity. Define custom error handling policies and recovery strategies per workflow step.
Deploy to Cloud, Edge, or On-Prem
Visual UI, CLI commands, or full CI/CD automation—your choice
Kubernetes
Native support
Cluster Mesh
Multi-region
CLI Deploy
Zero downtime
CI/CD Ready
Full automation
Deploy from UI
Visual deployment wizard

- Visual cluster selector with health status
- Drag-and-drop workflow deployment
- Live deployment progress tracking
Deploy from CLI
Scriptable automation
- One-command deployments with flags
- Shell-scriptable for automation
- Exit codes for pipeline integration
CI/CD Integration
GitHub Actions, GitLab CI, Jenkins, and more
- Automated rollbacks on failed health checks
- Blue-green deployments for zero downtime
- Canary releases with traffic shifting
- Pre/post deployment hooks for custom logic
Full-Stack Observability
Real-time metrics, distributed tracing, and event lineage tracking
Prometheus Metrics
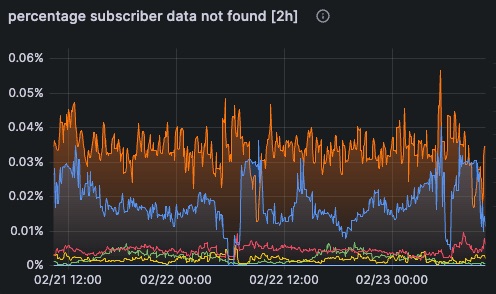
Throughput, latency percentiles, error rates, and custom business metrics. Visualize with dashboard of choice (e.g. Grafana).

Event Sniffing
Distributed tracing shows event flow across services. Trace a single event from Kafka to database, etc.

Audit Trails
Every event logged with detailed info. Debug production issues, prove compliance.
Open Source Meets Enterprise Ready
Start free, scale infinitely, integrate seamlessly

Start free, scale when ready.
Full reactive engine with unlimited nodes. Upgrade to Enterprise for larger volumes, premium support, and advanced security—no migration required.
Download Free
Integrate with your existing stack.
Protocol-based integration for Kafka, NATS, AWS Kinesis, databases (via JDBC), REST APIs, and more. Transform data on-the-fly with JavaScript, Python, or SQL.
Explore Integration Options
Designed for team collaboration.
User and role-based access control, and collaborative workflow development. From dev to prod with confidence.
Compare EditionsExplore Further
Dive deeper into use cases, comparisons, and detailed feature breakdowns
Who Is This For?
See how CTOs, Platform Engineers, Data Engineers, and Analytics Engineers use layline.io to solve their unique challenges.
Why layline.io?
Understand what makes layline.io different from traditional integration platforms and modern stream processing frameworks. Learn about our unique approach to event processing.
View ComparisonIndustry Solutions
Real-world implementations across finance, telecom, ecommerce, hospitality, manufacturing, and IoT.
Detailed Features
Explore the processors, oeprations, and advanced capabilities like clustering and deployment.
Browse All FeaturesPricing & Editions
Compare Community vs Enterprise editions. See detailed feature breakdowns, pricing, and support options.
Compare EditionsReady to Start?
Download Community Edition, schedule a demo, or talk to our team about your specific use case.
Get Started FreeTrusted by Industry Leaders
See how companies leverage layline.io to transform their data operations
"layline.io's reactive engine transformed how we process hotel bookings and guest data across 60+ properties. Real-time insights that were impossible before—now running 24/7 with zero downtime."
"The promise of being completely self-sufficient was kept at 100%. The ROI of the software is already evident a few weeks into production."


Learn More About layline.io
Technical articles, tutorials, and best practices from our engineering team
IBM Owns Confluent. Kafka Users Still Have a Runtime Problem.
The Kafka protocol is still open. The commercial center of gravity is not. Seven months after IBM closed Confluent, the questions that matter are dual-run, replay, and who owns batch when the streaming story is watsonx.
Streamhouse Is the New Buzzword. Here's the Part That Actually Matters.
Confluent, Aiven, and Redpanda want you to believe the streamhouse changes everything. It does change some things. But it doesn't fix the problem most teams are actually struggling with.
Data Products Fail When Nobody Owns the Runtime
Teams love calling their outputs 'data products.' But renaming a dashboard doesn't make it a product. The real test is who gets paged when it breaks at 2 AM — and whether they have the authority to fix it.