By Andrew Tan
The demo that never ages
Here is how the Iceberg pitch usually goes:
An engineer stands in front of a screen and runs a query against a Parquet dataset. Then they run the same query against an Iceberg table. The results are identical. The audience nods. Then the engineer shows time travel—rolling back to a previous snapshot—and the room actually murmurs. Somebody asks about schema evolution. The engineer adds a column, rewrites nothing, and the old queries still work. The committee is sold.
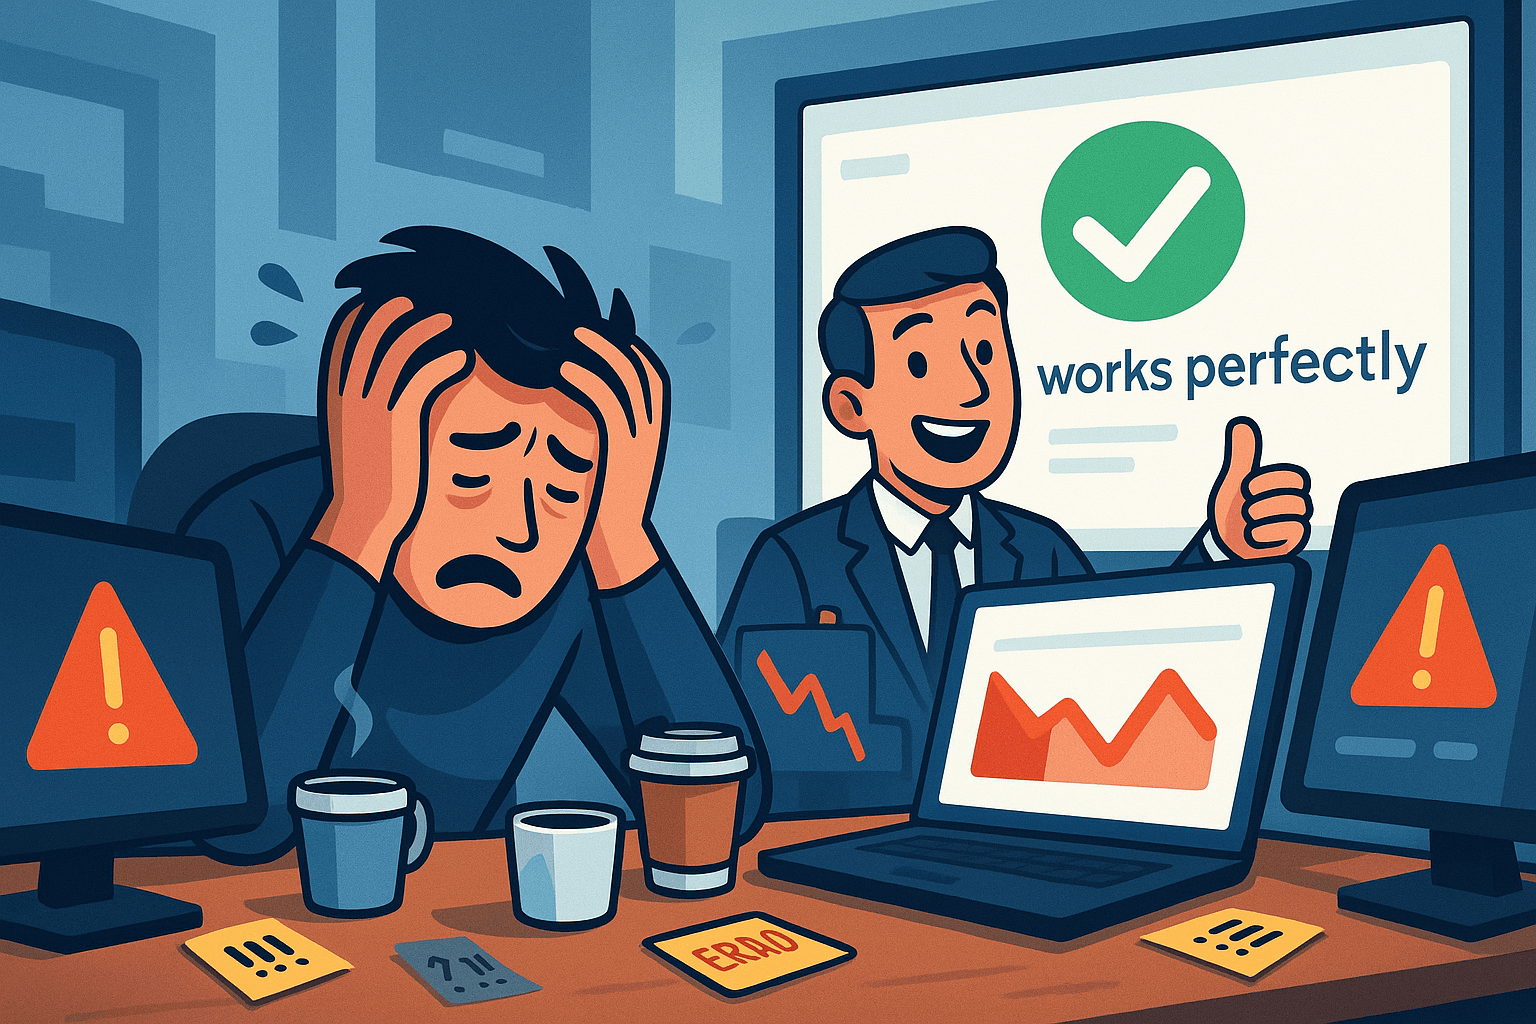
Six months later, the same team is in a different room. This one has no screen. Just a spreadsheet, a growing list of alerts, and a question nobody asked during the demo:
Who owns the compaction?
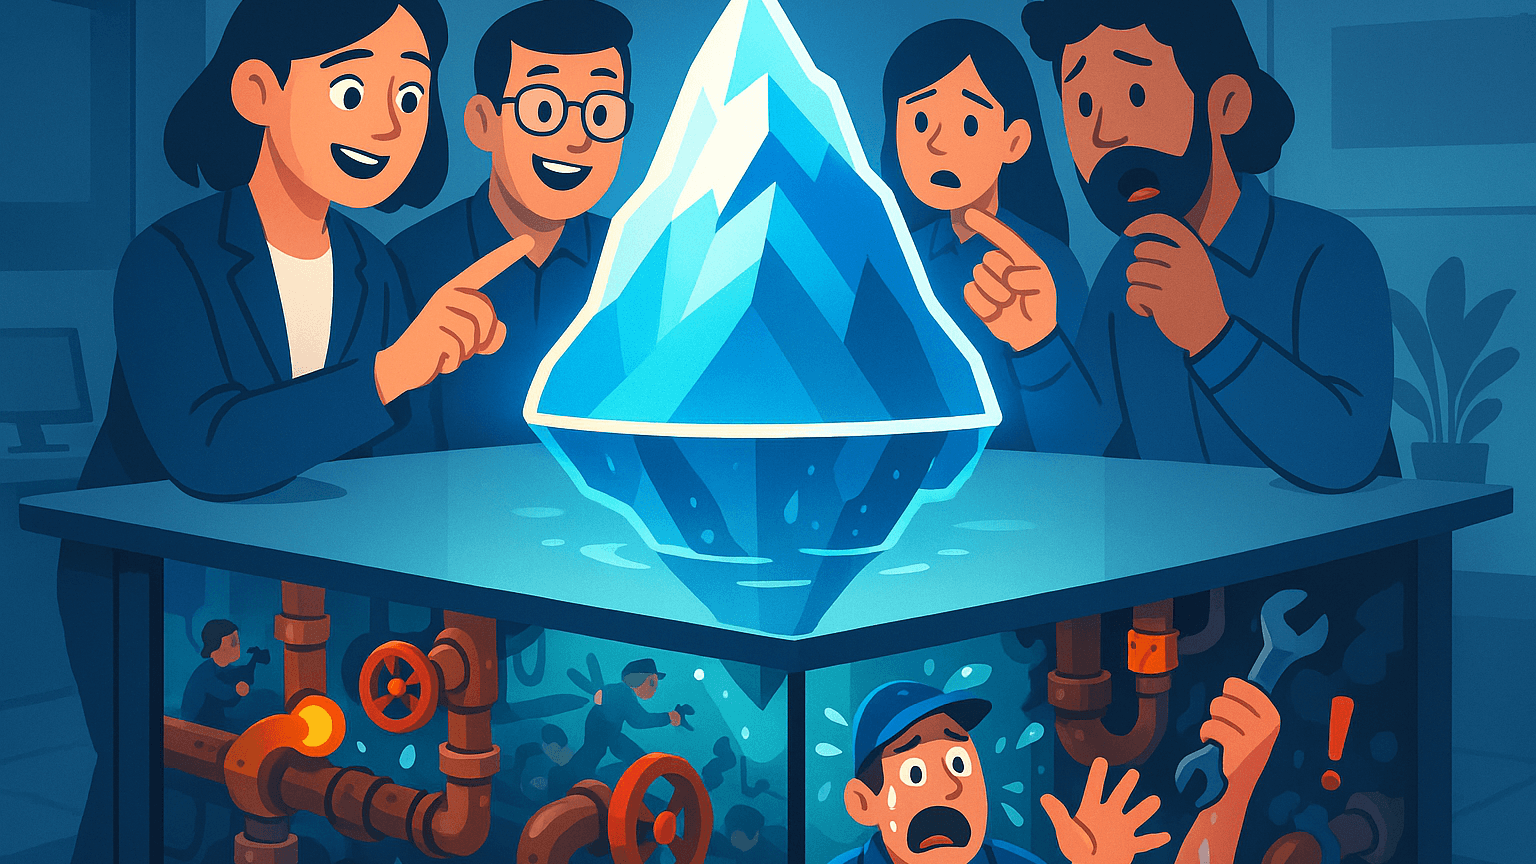
The demo showed what Iceberg makes possible. It did not show what Iceberg makes your problem.
What the spec promises vs. what the team inherits
Open table formats are a genuine advance. Portability across engines, snapshot isolation, partition evolution, and hidden partitioning are real capabilities that solve real pain. If you are trying to escape a vendor-locked warehouse, Iceberg, Delta Lake, and Hudi are the best paths out.
But the spec is not the system. The spec says how the metadata should be laid out. It does not say how your team should keep that metadata from growing without bound, how to coordinate compaction across multiple writers, or what happens when two different query engines disagree on which snapshot to read.
Here is what the demo skips:
Compaction is not automatic
Every insert, update, and delete creates new files and new metadata entries. Left alone, a high-velocity table accumulates thousands of small files. Query performance degrades. Metadata files bloat. The table that looked fast in the demo starts timing out in production. Somebody has to schedule compaction, monitor it, tune it, and handle the failures when two jobs try to rewrite the same partition.
Catalog sprawl is real
Iceberg tables need a catalog: Hive, Glue, Nessie, Polaris, a custom REST service. Each catalog has its own consistency model, its own authentication, its own upgrade cycle. A team that adopts Iceberg to avoid vendor lock-in often ends up managing two or three catalog systems instead of one warehouse. The lock-in shifts from the storage format to the catalog layer.
Retention policy is a distributed problem
When a snapshot expires, Iceberg marks the data as unreachable. But the underlying files still exist in object storage until something deletes them. That "something" is your problem. If you set aggressive retention to save on storage, you might lose the ability to roll back when a downstream job produces bad results. If you keep everything, your storage bill compounds while your S3 bucket turns into an archaeological dig.
Batch and streaming see different tables
A batch job writing to Iceberg produces large, well-structured files. A streaming job produces small, frequent files. If both paths write to the same table, the query planner has to handle two radically different file layouts. The streaming path needs frequent compaction to stay readable. The batch path needs stable files to avoid recomputation. Coordinating these two rhythms in one table is harder than the architecture diagrams suggest.
The demo showed a single writer and a single reader. Production rarely works like that.
Why "open" creates new fragmentation
The promise of open table formats is interoperability. Query the same data from Spark, Trino, Flink, DuckDB, Snowflake, BigQuery. In practice, each engine supports a different subset of the spec at a different maturity level.
One engine supports position deletes but not equality deletes. Another supports time travel but only for tables written by its own catalog. A third supports partition evolution but requires a specific metadata version that breaks older readers. The table is "open" in theory. In practice, it is coupled to the specific combination of engines and catalog versions your team happens to run.
This is not a criticism of the projects themselves. Iceberg, Delta, and Hudi are moving fast and improving rapidly. The issue is that teams adopt them expecting liberation and discover a new kind of operational surface area. Instead of one vendor to blame, they have a matrix of version compatibilities to manage.
The hidden cost is cognitive load. Your data engineers now need to understand not just their pipelines, but the compaction scheduling, catalog consistency model, metadata format version, and engine-specific behaviors of every tool that touches the table. That expertise does not come from a demo.
The checklist nobody runs before adopting
If your team is evaluating an open table format, here are the questions that matter more than query performance in a benchmark:
Who owns compaction, and what happens when it fails?
Compaction is not a one-time setup. It is a continuous background process that competes for the same compute resources as your production queries. If compaction falls behind, queries slow down. If compaction corrupts a partition, recovery is manual and stressful. You need an owner, a runbook, and a way to detect when compaction is not keeping up.
What is your catalog exit strategy?
Catalogs are the real lock-in point. If you commit to Glue today, can you migrate to Nessie or Polaris later without rewriting table paths and reconfiguring every downstream job? Most teams do not test this until they are forced to.
How do you handle late data and backfills?
Batch backfills and streaming late arrivals both rewrite historical partitions. Open table formats handle this better than raw Parquet, but they do not eliminate the coordination problem. If a backfill runs while a streaming job is appending to the same partition, you need to understand isolation semantics, retry behavior, and exactly what each engine does when it sees a conflict.
What is your metadata growth plan?
Metadata files are small but they multiply. A table with daily snapshots and hourly compaction can generate thousands of metadata files per month. Object storage is cheap, but LIST operations are not free. Some query engines load the full metadata tree into memory. At a certain scale, metadata itself becomes a performance bottleneck.
Who gets paged when a query returns wrong results?
Snapshot isolation is great until someone reads from the wrong snapshot because the catalog was briefly inconsistent. Or because a streaming job committed an incomplete batch. Or because two engines interpreted the same metadata file differently. Debugging these issues requires expertise in the format, the catalog, and the specific engine. The on-call rotation just got deeper.
If you cannot answer these questions with something more specific than "we'll figure it out," you are not adopting a technology. You are taking on a new operational domain.
Where the tradeoff is worth it
I want to be fair. There are situations where open table formats are the clear right choice:
You are actively escaping vendor lock-in.
If your warehouse provider is raising prices, deprecating features, or limiting egress, the portability of an open format is worth the operational overhead. The alternative is staying trapped.
You genuinely need time travel and rollback.
Some workloads—especially in regulated industries or financial services—require the ability to reconstruct historical state exactly. The snapshot model is not a nice-to-have here. It is a compliance requirement.
You run multiple compute engines on the same data.
If your analytics team uses Spark, your BI team uses Trino, and your ML pipeline uses DuckDB, a shared open table format eliminates the extract-transform-load dance between systems. The coordination cost is real, but it is lower than maintaining three separate copies of the same dataset.
You have the team for it.
If you have engineers who understand metadata formats, compaction strategies, and catalog consistency models, the operational burden is manageable. If you do not, you are outsourcing the expertise to consultants and hoping they stay available.
Where layline.io fits
At layline.io, we do not sell a table format. We sell a processing runtime that handles both batch and streaming workloads on the infrastructure you already have. That includes open table formats when they make sense, and traditional storage when they do not.
The reason this matters: a lot of teams adopt Iceberg because they need batch and streaming to coexist, and they have been told that open table formats are the only way to unify them. That is not true. The unification happens at the processing layer, not the storage layer. If your runtime can write well-structured files in batch mode and handle micro-batches in streaming mode—while managing compaction, backfills, and late data in the same workflow—the storage format becomes a configuration choice, not an architectural commitment.
We see teams who adopted Iceberg for the right reasons and then discovered that the hard part was never the format. It was the operational coordination around it: keeping batch and streaming paths consistent, handling schema changes without breaking downstream consumers, and making sure the same business logic produces the same results regardless of when the data arrives.
That is the problem we focus on. The table format is a detail. The operational model is what determines whether the system works at 2 AM on a Tuesday.
The question to ask before the demo
Next time a vendor shows you a slick Iceberg demo—time travel, partition evolution, engine switching that looks effortless—ask them this:
"Show me the compaction schedule. Show me the catalog failover. Show me what happens when a streaming job and a batch backfill hit the same partition. Show me the storage bill after six months of metadata growth. And show me who gets paged when a query engine reads a snapshot that was partially written."
If the answer is a reference to the documentation, you are looking at the easy part. The hard part is what you will own for the next three years.
Open table formats are not a scam. They are a real, valuable technology with a genuine operational cost that the marketing rarely mentions. The teams that succeed are the ones who price that cost upfront, assign ownership before the first table is created, and treat the format as one component of a larger operational system—not as a magic layer that makes infrastructure problems disappear.
The demo is the beginning. The maintenance bill is where the story actually starts.
If your team is weighing open table formats and trying to understand the full cost of ownership, get in touch. We work with teams on exactly this problem—and the operational reality is usually more manageable than the fear, once you know what to plan for.
Andrew Tan is a serial entrepreneur and founder of layline.io, building enterprise data processing infrastructure that handles both batch and real-time workloads at scale.