Insights & Updates
Articles, tutorials, and insights about data integration, event processing, and building scalable workflows.
Streamhouse Is the New Buzzword. Here's the Part That Actually Matters.
Confluent, Aiven, and Redpanda want you to believe the streamhouse changes everything. It does change some things. But it doesn't fix the problem most teams are actually struggling with.
Data Products Fail When Nobody Owns the Runtime
Teams love calling their outputs 'data products.' But renaming a dashboard doesn't make it a product. The real test is who gets paged when it breaks at 2 AM — and whether they have the authority to fix it.
dbt Is Leaving the Warehouse. Are Your Pipelines Ready?
dbt built the modern analytics workflow. Now the transformation layer is moving upstream — and the gap between SQL models and runtime execution is becoming the bottleneck nobody planned for.
Iceberg Is Easy to Demo. The Maintenance Bill Arrives Later.
Open table formats solve portability. They do not solve operations. The real work starts after the launch post: compaction, retention, multi-catalog sprawl, and keeping batch and streaming paths consistent.
Compliance Fails in Transit: Why Data Governance Has to Move Into the Pipeline
Most governance programs focus on data at rest. The real failure point is data in motion — CDC feeds, enrichment jobs, streaming joins, and AI-triggered workflows. Here's what governance looks like when you enforce it while the data is still moving.
Fresh Enough for an AI Agent? The Data Freshness Budget Nobody Defines
Most teams talk about AI context as a storage problem. The harder question is whether the data is fresh enough for the action the agent is about to take.
Why 85% of Enterprises Aren't Ready for AI
Fivetran's 2026 benchmark found 85% of enterprises running agentic AI on infrastructure that isn't ready. The model isn't the problem. The data pipelines feeding it are.
The Hidden Costs of Building Your Own Batch-Streaming Integration Layer
With AI-assisted coding, building your own data pipelines looks cheaper than ever. But the real costs aren't in the initial build—they're in the maintenance, the on-call rotations, and the accumulated complexity that compounds over time.
The Orchestration Market Is Consolidating. Here's Why That's Good News for Data Teams.
Dagster joining Prefect signals the end of standalone orchestrators. The winners will be unified platforms that combine orchestration and processing — and that's exactly where the market is heading.
CDC Is the Plumbing Everyone Forgets Until It Breaks
Change Data Capture is the invisible layer enabling real-time analytics and event-driven systems — but most teams only think about it after their first production incident
Your Data Warehouse Is Not Your Data Pipeline
Teams keep forcing their warehouse to do integration work it was never designed for. The result is ballooning costs, opaque failures, and architectures that become harder to maintain the more they 'succeed.' Here's the case for separating data movement from analytics storage.
The AI Productivity Gap: Why the Numbers Don't Add Up
Every enterprise dashboard claims AI is transforming the business. The actual productivity numbers tell a very different story — and understanding why matters for every team making AI investment decisions.
The AI Data Engineer: What Actually Changed (And What Didn't)
Every competitor blog is publishing 'AI is changing data engineering.' It's all breathless and vague. Here's the honest inventory — what LLM tooling genuinely helps with, what it still can't touch, and why the '80% automation' claims don't survive contact with production.
Data Contracts Are the API Versioning Your Data Pipeline Needs
Schema drift keeps breaking pipelines because we're monitoring for changes instead of enforcing contracts. Here's why data contracts are the missing layer between your producers and consumers.
Data Lineage Is a Vanity Metric Without Business Context
Most lineage tools produce beautiful diagrams that don't answer the one question that matters: 'What breaks if this data is wrong?' Here's how to move from observability theater to business-critical lineage.
Why I Stopped Believing 'Best Practices' and Started Trusting 'Works For Us'
I spent 18 months building the 'perfect' architecture. Then I watched a customer delete it in 20 minutes and replace it with a cron job. Here's what I learned about the 'best practice' trap — and why boring technology often wins.
What I Learned From Reading 50 Data Pipeline Postmortems
After analyzing 50 public postmortems from Uber, Netflix, Stripe, and others, four failure patterns emerge again and again. Most of them are preventable at the design stage.
You Didn't Escape Airflow's Complexity — You Just Distributed It
Adding Kestra, Dagster, or Prefect alongside Airflow doesn't reduce orchestration complexity. It multiplies it. Here's what the hidden coordination debt actually looks like — and what to do about it.
Why Your Data Team Can't Ship: The Organizational Bottleneck Nobody Talks About
The biggest blocker to data team productivity isn't technology—it's organizational friction. Here's how approval chains, toolchain fragmentation, and unclear ownership create bottlenecks that no amount of engineering talent can overcome.
Qlik Acquires Talend – Observations on Post-Acquisition Renewals and Alternatives.
Some Talend customers have reported significant increases in renewal pricing following Qlik’s acquisition of Talend. This article shares publicly available information and individual customer experiences and outlines what companies evaluating their options should consider.
What Happens to Your Pipeline When the Source System Changes Without Warning
Schema drift and upstream breaking changes are the number one cause of silent data failures. Here's how to stop getting blindsided.
What Happens to Your Pipeline When the Source System Changes Without Warning
Schema drift and upstream breaking changes are the number one cause of silent data failures — but most pipeline content focuses on infrastructure, not source system behavior
Financial Data Integration: A Practical Guide
What is financial data integration? Learn why integrating financial data is uniquely difficult, how it differs from regular ETL, and proven patterns teams use to solve it.
layline.io vs. Apache Kafka: When to Choose What
A practical comparison of stream processing approaches — covering latency, operational complexity, and the team fit that actually determines the right choice
Why Real-Time Data Integration Matters for Modern Applications
The difference between near-real-time and actually-real-time, and why the gap costs more than you think
Why Most Data Pipelines Fail at 3 AM (And How to Build Ones That Don't)
The real reasons production data pipelines break in the middle of the night — and the engineering practices that prevent it
The Streaming Migration Nobody Asked For
A data architect at a Fortune 500 once told me they spent 14 months migrating to Kafka — then quietly switched half the pipelines back to batch. Here's why that keeps happening, and what I'd do instead.
When Your Airflow Pipelines Need to Go Real-Time
You've got Airflow running. Your team knows it. The DAGs work. So why are you suddenly hearing 'we need real-time' — and what do you actually do about it?
Edge Processing That Actually Saves Money
How Local Data Filtering Can Cut Your Cloud Bill by 90% — And What Yours Could Look Like
From Batch to Streaming: A Practical Guide to Modern Data Pipelines
Why real-time data matters, what makes migration hard, and how to think about the transition — whether you choose layline.io or another path
Your Cloud Bill Called. It Wants a Word About Serverless.
From invisible scaling to invisible invoices—why engineering teams are ditching FaaS for persistent, predictable data engines.
Discover the Power of Apache Pekko with layline.io
At layline.io, we've harnessed the robust capabilities of Apache Pekko to bring you a comprehensive low-code event-processing platform. With our solution, you can leverage the full potential of Apache Pekko without writing a single line of code.
The Power of Data Orchestration with layline.io: A Ubiquity Unifi Showcase Scenario
In an age where data rules supreme, managing and orchestrating the vast sea of information has become the backbone of numerous businesses and industries.
layline.io: Revolutionizing Hamburg's IT Startup Scene with Event Data Processing Expertise
layline.io selected one of the most influential IT-Startups in Hamburg, Germany by EU Startup News.
H-Hotels.com - Digital Transformation with layline.io
The hospitality industry has seen significant technological advancements in recent years. This includes data integration software being one of the most critical tools that the industry can leverage to optimize their operations.
The Advantage of Event-Based Asynchronous Data Processing
In today's fast-paced world, every business is looking for better ways to process large volumes of data. Traditional data processing methods have their limitations, which is why companies are increasingly exploring event-based asynchronous data processing.
layline.io - A Kafka Comparison
How does layline.io compare to Kafka? This is a question which we hear from time to time. We wonder why.

Sample Series: Http-Client-Requests
ReST interfaces are popular and abundant. We show you how to configure Http-Client requests within layline.io using Yahoo Finance as an example.
Sniffing Real-Time Data
It's hard to understand what's actually happening in complex processing scenarios. layline.io helps by providing probing tools to get insights into inner workings of complex Workflows at runtime.
ASN.1 Format Configuration
ASN.1 is still a popular data format. Learn how easy it is to configure any ASN.1 format in layline.io.
Damn that Data Format Hell
Dealing with complex data formats and changes can be daunting. Learn how layline.io tackles this challenge using a configurable grammar language.

Output to Kafka
Showcase on how to read data from a structured file, map record data, and output the data Kafka cloud.
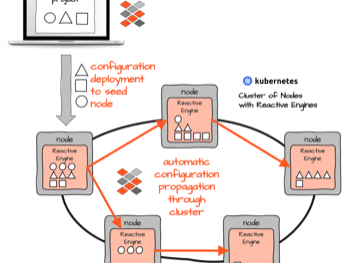
Advantage of layline.io Workflows compared to traditional Microservices using the K8S/Docker model
The traditional Microservices model on Kubernetes/Docker has some disadvantages which result in overly complex management and resource consumption. We explain the background and how layline.io can help.
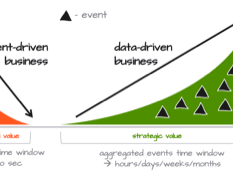
Event-driven or bust!? Are you missing out if your business is not event-driven?
You may be missing out if you are data-driven only. In fact, every business is data-driven. But you should ask yourself what that really means, and whether it is sufficient for you tomorrow.
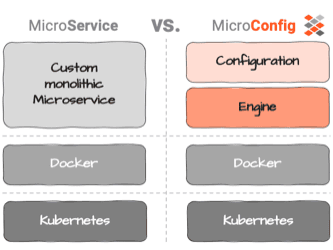
Fixing what's wrong with Microservices
For some years now Microservices and Service-oriented architectures have been all the rage. But there are downsides. Can they be overcome?
Dealing with data-pressure in message-based systems
How to deal with data pressure in non-stop message-driven solutions and ensure non-stop uptime under load.
Stay Updated
Get the latest articles, tutorials, and updates delivered straight to your inbox.
No spam. Unsubscribe anytime.